Last year I
published some
Writer training slides, which are hopefully a useful extension to in-tree
documentation like
sw/README and
sw/qa/extras/README.
Last week I reviewed those slides and realized that some of them are outdated. So here comes an updated version:
The intention is that these build nicely on top of Michael's
generic intro slides,
and with that, the reader can have a good "big picture" understanding of the
code base. For the gory details, you always need to read the code anyway. ;-)
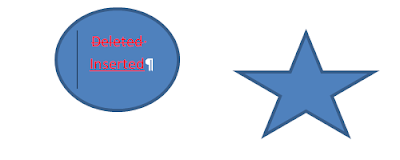
Shapes in Writer are provided by LibreOffice's drawing layer -- they are
independent from the normal Writer paragraphs. Given that the drawing layer
does not support tracking changes, just Writer's "native" paragraphs, fully
featured tracked changes in real shape text would be quite some work. In case
of ODF, the markup describes tracked changes in a way, so that in case the
reader does not support tracking changes, it can at least read the normal and
inserted text, i.e. the current version.
This is exactly what I
implemented
in the DOCX import filter now:
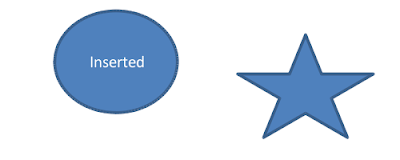
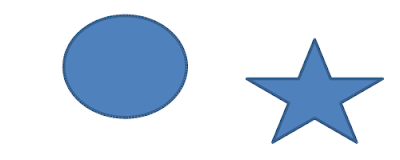
Previously we just ignored both inserted and deleted text, so if you had
content which was all either deleted or inserted, you ended up having no shape
text at all (can be tested using e.g.
this
test document):
OTRS is quite different to Bugzilla (what we use for upstream LibreOffice
development for quite some time). On the plus side, e.g. it has strong support
for multiple customers. OTOH, it deals with tickets instead of bugs, and sadly
it doesn't have a single identifier for tickets. It has a ticket number
(which by default even includes the date), which is searchable, and it has a
ticket ID, which is used for URL's.
In case of Bugzilla, you can easily lookup "bug#12345" in Firefox. Create a
bookmark with the following properties:
and then you can just copy&paste bug#12345 to Firefox, replace the # with a
space, and Firefox will do the right thing.
Unfortunately (due to the above detailed reasons), this is not possible with
OTRS. So I decided to write a Supybot plugin that can notice "bug#12345" on an
IRC channel, and give you the clickable URL (after finding out the ticket ID
from the ticket number).
The result is available
on GitHub,
it looks like this:
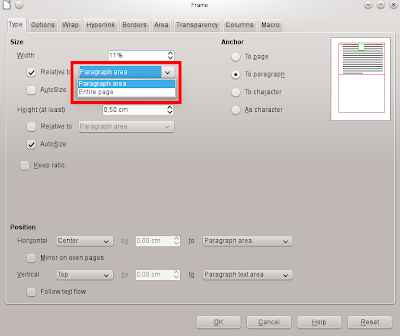
When using text frames in Writer, you can always choose if you set an absolute
size for it or you set a relative one. Oddly enough, in case of relative
sizes, it wasn't entirely clear what 100% percent means. With a bit of
searching, the help says
"it's the page text area", which in practice means the page size, excluding
the margins.
And that's where the problem lies: in many cases (importing foreign formats,
cover page of a document, etc.) you want to have a textframe which is 100%
wide, compared to the full page size, including margins. It was already
possible previously to work this around by manually specifying the same size
what was used for page size, but that's ugly, you duplicate the setting at two
places.
As you can see on the above screenshot, in LibreOffice 4.3, I now implemented
this as a new option, you can choose what 100% means for both width and
height. File filters are also updated accordingly: in case of ODF an
extension
is proposed, and also DOCX and RTF filters are updated, where the file format
already supported this feature.
For the curious ones, the feature is in master for almost two months now,
but I only implemented my favorite part -- RTF filter -- only last week,
that's the "news" here. ;-)
If you want to try these out yourself, get a
daily build and play with it! If
something goes wrong, report it to us in the
Bugzilla, so we can try fix it
before 4.3 gets branched off. Last, but not at least, thanks for
CloudOn for funding this improvement! :-)
I'm sure in this case a few words are worth more than the above picture, so
let me describe what you see above. :-)
In case of opening an ODT, DOC or RTF document in LibreOffice Writer, you
already got some feedback on where the importer is, in case the process needed
more time than what you feel "instant". However, this wasn't supported for
DOCX. According to git blame, I added this to my todo on 2012-10-29, and a
few months later also a
bugreport was opened,
requesting the same, but up to yesterday, nothing changed. However, now I've
implemented this on master, it'll be part of the 4.3 release.
Back to where I started, what you actually see there is when LibreOffice is in
the middle of the import process of the Holy Bible in DOCX format, which takes
around 12 seconds on my machine. One could say that speed up quite acceptable
for that amount of data, but with a progressbar, it's definitely better. ;-)
Last year in September we
decided
to get rid of the writerfilter-based DOC tokenizer, and I volunteered to
actually do this. As cleanups in general have a low priority, I only
progressed with this slowly, though yesterday I completed it, that's why I'm
writing this post. :-)
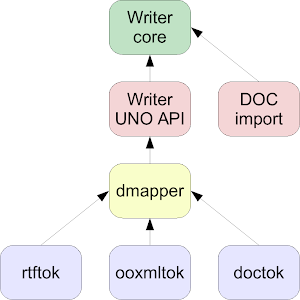
Some background: the writerfilter module is responsible for RTF and DOCX
import in Writer. As the above picture shows, the currently used DOC import is
independent from it, and there was also an other DOC import filter, that was
in writerfilter which was disabled at runtime. As I don't like duplication, I
examined the state of the two filters, and the linked minutes mail details
how we decided that the old filter will stay, and we'll get rid of the
writerfilter one. It's just a matter of deleting that code, right? :-) That's
what I thought first. But then I had to realize that the architecture of
writerfilter is a bit more complex:
the dmapper (domain mapper), that handles all the nasty complexities of
mapping Word concepts to Writer concepts (think of e.g. sections ↔ page
styles)
one tokenizer for each (RTF, DOCX, DOC) format
The traffic between the tokenizers and dmapper is called tokens. Naturally
it's not enough that tokenizers send and dmapper receives these tokens, they
should be defined somewhere as well. And that's where I realized this work
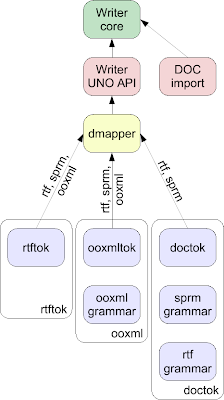
will take a bit more time: instead of having a single token definition,
actually the ooxml tokenizer defined its own grammar, and doctok also defined
two additional grammars. And of course dmapper had to handle all of that.
;-) Given that OOXML is a superset of the DOC/RTF format, it makes sense to
just use the ooxml grammar, and get rid of the other two.
Especially that -- by now you probably found this out -- if I wanted to kill
doctok, I had to kill the sprm and rtf grammars as well. Otherwise just
removing doctok would break the RTF and DOCX import as well, as those also
used the rtf/sprm grammars.
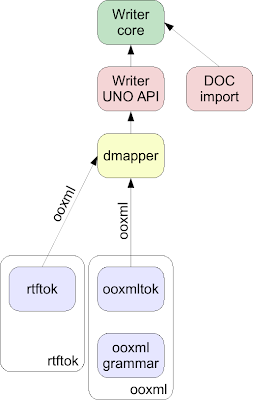
So at the end, the cleaned up architecture now looks like this:
It removes quite some code: In libreoffice-4-1, the doctok was 78849 (!)
lines of code (well, part of that was XML data, and some scripts generated
C++ code from that).
dmapper now doesn't have to handle the rtf and sprm grammars anymore, so now
there is a single place in dmapper that handles e.g. the italic character
property.
Smaller writerfilter binary for the end user: even if doctok wasn't enabled
at runtime, it was shipped in the installation set.
Hopefully it's now a bit more easy to understand writerfilter: at least e.g.
if you want to look up the place where dmapper handles the character bold
("b") XML tag of OOXML, you don't have to know that the binary DOC
equivalent of that is sprmCFBold, just because we have an unused DOC tokenizer
there as well. :-)
Given that DOC and RTF formats are a dead end, I think it's a good thing
that in writerfilter now the grammar is OOXML (that keeps introducing new
features), rather than some dead format. ;-)
If you ever tried to use nested comments in Writer (make a selection, Insert
-> Comment, then make an overlapping selection, and do it again), you may have
noticed that only the ODF filter can load and save such a document properly.
Recently I have improved this situation a lot. Motivated by seeing this is now
supported in the DOCX import filter, I now added support for this also to the
DOCX export, RTF import/export and binary DOC import/export filters.
If you want to try this out, core.git has a
ODT
and
DOC
samples to play with.
I was also happy to meet Jacobo, Matus, Tim and Tomaž finally personally. :-)
Quite some other slides are now available on
Planet, don't miss them. I also took
some pictures, available
here,
including photos of all speakers in our devroom.
Although LibreOffice 4.2.0 is
not yet released, it was
already branched off from master in November last year, and improvements for
the next release are already cooking in master. One of these will be a major
improvement of shape handling in the DOCX import/export filter.
Some background: when DOCX was initially introduced, it still used
VML (which is in short
an XML equivalent of the binary shape format), and only Word 2010 started to
write shapes using
drawingML.
Given that Word still understands VML, it wasn't urgent for us to write shapes
using the drawingML markup. As for import, Word still writes an approximate
version of the shape in VML as a fallback -- that's what we read till now.
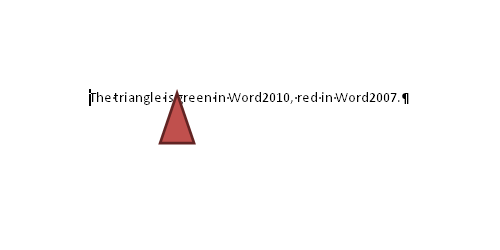
Needless to say, newer drawingML features have no VML equivalent so with time
it became more and more important for us to finally read and write shapes in
DOCX using drawingML, which just happened in Writer.
I'm posting here a few screenshots showing the improvements I've implemented.
Note that final 4.3 is still far from being released, so this is not a
complete list. :-) In each case I'm providing a screenshot showing how it
looked (at the end of an import/export/import again roundtrip) before, how
it looks now in 4.3 and the reference layout. Click on the images to get a
larger image:
If you want to try these out yourself, get a
daily build and play with it! If
something goes wrong, report it to us in the
Bugzilla, so we can try fix it
before 4.3 gets branched off. Last, but not at least, thanks for
CloudOn for funding these improvements! :-)