TL;DR: Import of annotated text ranges from binary DOC format was a problem
for quite some time, now it should be as good as it always was in the
ODT/DOCX/RTF filter.
Longer version: the import of annotation marks from binary DOC was never
perfect. My
initial
implementation had a somewhat hidden, but important shortcoming, in the form
of a "Don't support ranges affecting multiple SwTxtNode for now." comment. The
underlying problem was that annotation marks have a start and end position,
and this is described as an offset into the piece table (so the unit was a
character position, CP) in the binary DOC format, while in Writer, we work
with document model positions (text node and content indexes, SwPosition), and it isn't
trivial to map between these two.
Tamás somewhat
improved
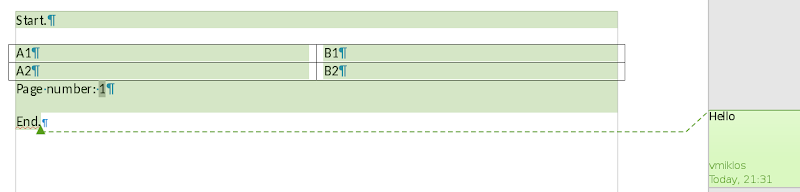
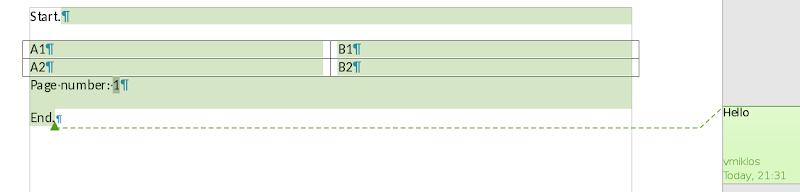
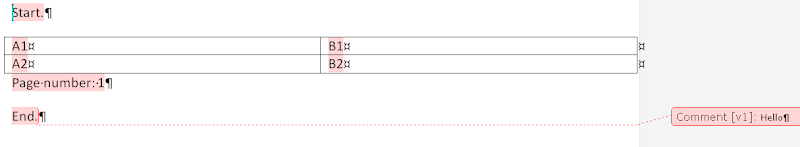
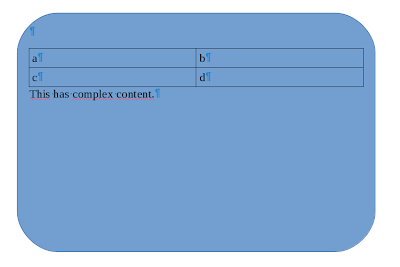
this homegrown CP -> SwPosition mapping code, but was still far from perfect. Here is an example. This is how this demo document looks like now in LibreOffice Writer:
The reason is that the document has fields and tables, and the homegrown CP ->
SwPosition mapping did not handle this. A much better approach is to handle
the mapping as we do it for bookmarks: even if at the end annotation marks and
bookmarks are entires in sw::mark::MarkManager, it's possible to set the
start position as a character attribute during import (since mapping the
current CP to the current SwPosition is easy) and when we know both the
start and end, delete the character attribute and turn it into a mark manager
entry. That's exactly what I've done. The first screenshot is the result of 3
changes:
Hopefully this makes LibreOffice not only
avoid
crashing on such complex annotated contents, but also puts an end to the
long story of "annotation marks from binary DOC" problems.
NOTE: Just like how C++11 perfect forwarding isn't perfect -- if you think
it is, see "Familiarize yourself with perfect forwarding failure cases." in
this
post of Scoot -- the above changes may still not result in a truly perfect
import result of DOC annotation marks. But I think the #1 problem in this area
is now solved. :-)
TL;DR: If you touch the ODF and/or OOXML filters in LibreOffice, please use
the --with-export-validation configure option after you ran the
setup.sh
script.
Markus Mohrhard did an excellent job with
adding the --with-export-validation build switch to LibreOffice. It does the
following:
it validates every Calc and Impress zipped XML document (both ODF and
OOXML) produced during the build by export filters
it does the same for Writer, except there only a subset of documents are
validated
One remaining problem was
that it required setting up both
odfvalidator
and officeotron, neither of them are
standard GNU projects but Java beasts. So even if I and a number of other
developers do use this option, it happens from time to time that we need to
fix new validation regressions, as others don't see the problem; and even if
we point it out, it's hard to reproduce for the author of the problematic
commit.
This has just changed, all you need is to get export-validation/setup.sh
from dev-tools.git, and run it like this:
./setup.sh ~/svn /opt/lo/bin
I.e. the first parameter is a working directory and the second is a directory
that's writable by you and is already in your path. And then wait a bit... ODF
validator uses maven as a build system, so how much you have to wait depends
on how much of the maven dependencies you already have in your local cache...
it's typically 5 to 15 minutes.
Once it's done, you can add --with-export-validation to your autogen.input
and then toplevel make will invoke odfvalidator and officeotron for the
above mentioned documents.
The new year is here, if you don't have a new year's resolution yet -- or if
you hate those, but you're willing to adopt a new habit from time to time --
then please consider --with-export-validation, so that such regressions can
be detected before you publish your changes. Thanks! ;-)
TL;DR: see above -- a number of preset shapes are now rendered correctly at
any scale factors, where previously rendering problems occurred.
fdo#87448 has a reproducer
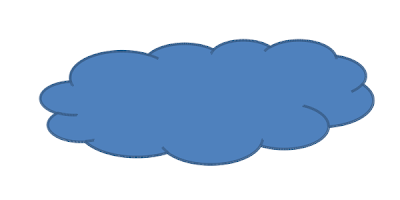
document that shows rendering errors with the scaled cloud preset shape
definition. At first I thought that the OOXML spec has wrong definition for
this shape type, but that turned out to be not the case. What was a problem is
our implementation of the drawingML arcTo command. This implementation defines
how we render such arcs as polygons when the shape is to be painted, and given
that LibreOffice has native support for the drawingML arcTo / ODF G command,
this implementation is invoked during rendering, it's not an import/export
problem.
The cloud is drawn using a set of moveTo and arcTo commands. MoveTo is easier,
as it uses explicit coordinates, but arcTo is more complex. It has 4
parameters: the height and width of a "circle", and the start / end angle of
an arc on that circle. (Of course if height and width do not equal, than
that's no longer a circle... ;-) ) The problem is that due to this, the
distance vector between the arc's start and end points is implicit -- so if
something is miscalculated, errors are nicely added to each other as more and
more arcs are drawn. This is especially a problem if you later return to the
end of an earlier arc using moveTo: if arcTo has some problem, then it'll be
clearly visible.
After
fixing UNO ARCANGLETO to only take care of scaling / translation only after counting
the actual arc, we started to produce correct end points for the arcs and
shapes started to appear correctly at any scale factor, yay! :-)
One remaining problem was how to test this from cppunit, in the above commit I
exported the shape to a metafile, and then I could use Tomaž's excellent
MetafileXmlDump to assert that the end of an arc (implicit location) and the
parameters of a moveTo command (explicit location) equal -- when they do not,
that's what your eyes call a "rendering problem".
As someone who usually hacks on LibreOffice, external import filters produced
by the Document Liberation Project cut both ways: they are great, as they deal
with obscure formats and we get them for free, OTOH hacking such code is more
complex than the usual LO code. I recently contributed a few patches to
libvisio
and
libodfgen,
but before I was able to do actual code changes, I had to set up a number of
repositories and configure them to talk to each other -- this post describes one
possible setup that suited my needs.
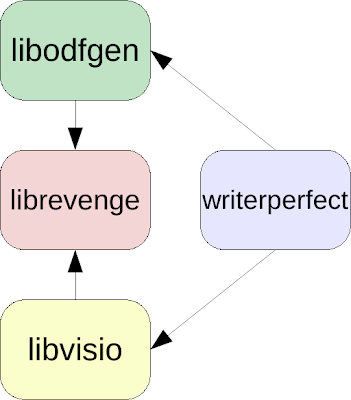
DLP's central project is librevenge and everything builds on top of that,
either by calling it or called by it. In case the task is to turn VSDX files
into ODG ones, it looks like this:
libvisio can build a librevenge document model from Visio files (more on the
various librevenge-based libraries
here),
libodfgen can generate ODF output from such document models (one other
possibility would be e.g.
libepubgen), and the
writerperfect module provides kind of a controller for the remaining modules,
e.g. for our purpose, a vsd2odg binary.
One possibility is to build LibreOffice, use --with-system-libvisio and
similar switches, then clone the repos, install them system-wide (possibly
with your modifications), and then you can test your changes just with
building the various libs, without changing your LO build (more
here).
The drawback is that this way you pollute your system with unstable versions
of those libs.
An other possibility is to build LibreOffice as usual, and then use the
external
libraries patching mechanism to hack on the code. The drawback is that you
have to work without git on the code, and also you can only work with a
released version.
So here is what I did to avoid the above mentioned drawbacks: all DLP projects
use pkg-config to find the required libraries, so you can configure them in a
way that allows building as a user, avoid installing them at all, and still
execute vsd2odg using the libs with your changes. Here is how to do it:
librevenge:
git clone git://git.code.sf.net/p/libwpd/librevenge
cd librevenge
./autogen.sh
./configure --enable-debug
make
libvisio:
git clone git://gerrit.libreoffice.org/libvisio
cd libvisio
./autogen.sh
./configure REVENGE_CFLAGS="-I/home/vmiklos/git/libreoffice/librevenge/inc" REVENGE_LIBS="-L/home/vmiklos/git/libreoffice/librevenge/src/lib/.libs/ -lrevenge-0.0" REVENGE_GENERATORS_CFLAGS="-I/home/vmiklos/git/libreoffice/librevenge/inc" REVENGE_GENERATORS_LIBS="-L/home/vmiklos/git/libreoffice/librevenge/src/lib/.libs/ -lrevenge-generators-0.0" REVENGE_STREAM_CFLAGS="-I/home/vmiklos/git/libreoffice/librevenge/inc" REVENGE_STREAM_LIBS="-L/home/vmiklos/git/libreoffice/librevenge/src/lib/.libs/ -lrevenge-stream-0.0" --enable-debug --enable-werror
make
libodfgen:
git clone git://git.code.sf.net/p/libwpd/libodfgen
cd libodfgen
./autogen.sh
./configure REVENGE_CFLAGS="-I/home/vmiklos/git/libreoffice/librevenge/inc" REVENGE_LIBS="-L/home/vmiklos/git/libreoffice/librevenge/src/lib/.libs/ -lrevenge-0.0" REVENGE_STREAM_CFLAGS="-I/home/vmiklos/git/libreoffice/librevenge/inc" REVENGE_STREAM_LIBS="-L/home/vmiklos/git/libreoffice/librevenge/src/lib/.libs/ -lrevenge-stream-0.0" --enable-debug
make
Of course, replace /home/vmiklos/git/libreoffice/ with any other directory
you like, just be consistent. ;-)
Now you can hack on any of these libraries, you just need to build your
changes, and then vsd2odg will produce a flat ODG that you can quickly test
with any ODF processor, like LibreOffice. One remaining trick (in case you're
not an autotools expert) is that vsd2odg is a libtool shell script, not a
binary. If you still want to run the underlying binary in gdb, here is how you
can do that:
It turns out LibreOffice's RTF and DOCX import filter ignored borders around Writer
pictures. Given that this
worked in the RTF case in
the past, it's a bit amusing that now the very same commit implements a new
feature for the DOCX case and at the same time fixes a regression in the RTF
filter. Code sharing FTW! :-)
UPC traditionally had a setup
consisting of a cable modem providing internet access to a single computer,
and then it was up to the users if they use that access to really connect to a
computer or to a router, providing wireless access and so on. It seems, these
days they are more after actually encouraging people to use their
subscription on multiple devices -- possibly that way it's easier to sell
larger packages (like 60 MBit/s download rate instead of 30 MBit/s, etc). One
fallout from this move is that they started to replace modems with a
combination of modems and routers, in this case this is an
Ubee EVW3226, with the
brand removed. I wanted to try out if this new device could replace my
previous router or not -- so far it seems to be good enough, though there was
one pitfall, hence this post.
It's possible to define a range of IP addresses to be used for DHCP purposes,
though you can't serve fixed IP addresses based on the MAC address of the
clients. Given that my home network isn't that large, I can tolerate that: as
long as there is a range that can be safely used for fixed addresses, I can
configure that manually. It's also possible to do port forwarding, e.g.
redirecting the incoming ssh traffic to a given address -- except you can't do
both at the same time: you can't redirect traffic to an address that's not
known (served via DHCP) to the router. Which is a shame, the #1 use case for
port forwarding is to redirect traffic to a home-server that will then also
have a fixed IP internally...
So here is a hack that allowed me to still do this: set the start of the range
of the DHCP served IP's exactly to the address of the (to be used in future
as) fixed address, e.g. 192.168.0.5. Connect with one client, so that the
address will be known to the router. Then add the port-forwarding rule,
finally set the DHCP range back to its original value (in my case I use
192.168.0.1..99 for fixed addresses and 100+ for dynamic purposes). It's a
stupid trick, but it works... ;-)
In June, we
decided
to get rid of XSLT usage in writerfilter, the module responsible for RTF and
DOCX import in LibreOffice. As usual with cleaning up mess, this took time
(about two months), but I'm now happy to say that I'm mostly done with this.
:-)
See the doctok blog post for some
background, the topic here was to clean up the OOXML tokenizer, that is that
building block that turns a zipped XML document into a token stream.
The following problems are now solved:
Part of the module was generated code, the generator was implemented mostly
in XSLT, but some bits were written in Perl and sed. About 4200 lines of
XSLT code is now rewritten in Python, in about 1300 lines.
Given that we have much more developers who speak Python, compared to XSLT,
nontrivial changes are now much easier in the generator: Jan Holesovsky
cleaned
upboost::unordered_map usage at places where we depended on the order of
elements. (Yes, you read it correctly, that was the situation up till now!)
This also helps reducing the size of the resulting writerfilter shared library.
The input of the code generator was the large model.xml file, and
generator scripts only extracted interesting information from it, so if you
mistyped something, you got no error messages, just silent failures. I've
removed quite some XML elements and attributes from it which were parsed by
none of the generator scripts and written a
relax-ng
schema for the remaining markup. Validating against this schema is part of
the default build, so no more typos without a build failure. ;-)
(The schema also contains quite some documentation, finally.)
A gperf hash of all possible OOXML elements / attribute names were
duplicated in writerfilter, even if that information was already available
from the oox module. This is now fixed, reducing the size of the shared
library even further.
Also, both oox and writerfilter had a list of namespace URL's, mapping them
to an integer enumeration, and when the two lists didn't match, Bad Things
happened (read: usually resulted in a crash.) This is the past, I've
refactored writerfilter to use the same namespace alias names as oox, and this
allowed to get rid of the writerfilter copy of the namespace alias list. So in
the future, if new namespaces have to added, only oox has to be extended.
Oh and the bonus feature: I've implemented a script called
watch-generated-code.sh,
which can record a good state of the generated code, and then compare later
generated results against that, so that refactoring of the generator can now be
performed in a safe way: you can change the generator in any way to make it
better, and still avoid accidental output changes. :-) This is particularly
useful, as it only diffs the end result of the whole generation process (cxx
and hxx files), not temporarily files, which are OK to change, as long as the
end result is the same.
As a conclusion, here are sizes of a stripped dbgutil version of the
writerfilter shared library, from the libreoffice-4-3-branch-point and today's
master:
From time to time developers feel that they have little time, but they would
want to take care of many bugs. Last week I was frustrated enough to actually
design a T-shirt for just that. ;-)
Above is how it looks like. In case you don't get the joke, see
here
for a hint. Oh, and if you would like to build your own binary... err T-shirt,
you can do it:
here is the ODG
file that can serve as a source. Happy bugfixing! :-)
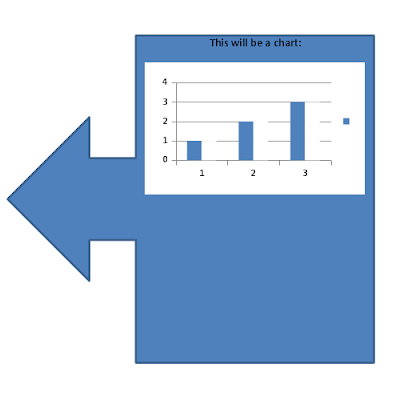
TL;DR: see above -- it's now possible to have complex Writer content (charts,
tracked changes, tables, fields, etc.) inside drawinglayer shapes, yay! :-)
Writer in LibreOffice 4.3 can have two kind of shapes: drawinglayer ones or
Writer TextFrames. (Let's ignore OLE objects and Writer pictures for now.)
Drawinglayer shapes can be triangles (non-rectangular), rectangles can have
rounded corners and so on, but shape text is handled by editeng -- the same
engine that is used for Impress shapes or Calc cells. OTOH a Writer TextFrame
can contain anything that is supported by Writer (Writer fields, styles,
tables, etc.), but its drawing capabilities are quite limited: no triangle,
rounded corners, etc. Together with CloudOn, we
thought the best would be to be able to have both, and started to use the
"shape with TextBox" term for this feature.
A user can already sort of to do this by creating a drawinglayer shape, then a
Writer TextFrame, and by setting the properties of the Writer TextFrame
(position, size, etc) to appear as if the TextFrame would be the shape text of
the drawinglayer shape. The idea is to tie these two objects together, so the
(UI and API) user sees them as a single object.
What follows is something you can probably skip if you're a user -- however if
you're a developer and you want to understand how the above is implemented,
then read on. ;-)
From the drawinglayer point of view: SwDoc contains an SdrModel
(SwDoc::GetOrCreateDrawModel()), which contains a single SdrPage
(SdrModel::GetPage()) -- Draw/Impress contain multiple sdr pages. The
SdrPage contains the shapes: e.g. a triangle is an SdrObjCustomShape. For
TextFrames, a placeholder object called SwVirtFlyDrawObj is added to the
draw page.
The writer-specific properties of an SdrObject is stored as an SwFrmFmt
object, an SwFrmFmt array is a member of SwDoc ("frame format table"). The
anchor position and the node index of the frame contents counts as a property.
At UNO level, a single DrawPage object is part of the Component (opened
document), which abstracts away the internal SdrPage.
For TextFrames, the UNO API works exactly the same way, except that the
implementation stores all properties of the TextFrame in the SwFrmFmt (and
some properties are different, compared to a drawinglayer shape).
One remaining detail is how the shape text is represented. In case of
drawinglayer shapes, this is provided by editeng: internally an EditTextObject
provides a container for paragraphs, at UNO API level SvxUnoTextContent
provides an interface that presents paragraphs and their text portions.
For TextFrames, the contents of the frames is stored in a special section in
the Writer text node array (in the 3rd toplevel section, while the 5th
toplevel section is used for body text), that's how it can contain anything
that's a valid Writer body text. An offset into this node array of the
"content" property of the SwFrmFmt.
At a document model level, we need a way to describe that an SdrObject
(provided by svx) has an associated TextFrame (provided by sw). svx can't
depend on sw, but in the SwFrmFmt of the SdrObject, we can use the so far
unused RES_CNTNT ("content") property to point to a TextFrame content.
So behind the scenes the UNO API and the UI does the following when
turning on the TextBox bit for a drawinglayer shape:
creates a TextFrame
connects the SdrObject to the TextFrame
Also, every property of the TextFrame depends on the properties of the
SdrObject, think of the followings:
position / size is the largest rectangle that fits inside the shape
borders are disabled
background is transparent
Finding the largest rectangle that fits inside the shape is probably the most
interesting here, it's implemented in SwTextBoxHelper::getTextRectangle(),
which uses SdrObjCustomShape::GetTextBounds().
The UNO API hides the detail that the TextFrame and the SdrObject are in
fact two objects. To get there, the followings are done:
SwXShape is modified, so that in the TextBox case not editengine, but the
attached TextFrame is accessed when getText() is invoked.
This was a bit tricky, as SwXShape doesn't have an explicit getText()
implementation: it overrides queryInterface() instead (see
SwTextBoxHelper::queryInterface()).
SwXDrawPage (its XEnumerationAccess and XIndexAccess) is modified to
ignore TextFrames in the TextBox case
SwXTextPortionEnumeration is modified to ignore TextFrames in the TextBox case
SwXText::insertTextContent() and SwXText::appendTextContent() is
modified to handle the TextBox case
This was the easiest part: the "merge TextFrame and SdrObj into a shape with
TextBox" approach ensured that that we use existing layout features here, no
major effort was necessary here.
One interesting detail here was the positioning of as-character anchored
shapes having TextBoxes, that's now handled in SwFlyCntPortion::SetBase().
The primary point of this feature is to improve Word (and in particular DOCX)
compatibility, and of course I wanted to update ODF as necessary as well.
Regarding the new feature, I did the followings:
DOCX import now avoids setting service name from original to
css.text.TextFrame in case shape has shape text
DOCX export now handles the TextBox case: reads Writer text instead of
editeng text as necessary
If you want to try these out yourself, get a
daily build and play with it! If
something goes wrong, report it to us in the
Bugzilla, so we can try fix it
before 4.4 gets branched off. Last, but not at least, thanks for
CloudOn for funding these improvements! :-)